🔍 Read the full analysis: The Cost And Caveat Of Meta’s Muse Ember AI on ThorstenMeyerAI.com

Get the little things that make your day delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Meta released Muse Ember on November 9, 2026, as a lower-cost model for API use and its Muse Code coding agent. Artificial Analysis measured it at the same Intelligence Index score as Claude Haiku 5.5, with a lower average cost per index task, but found much lower factual accuracy and frequent refusals.
Meta released Muse Ember on November 9, adding a lower-cost model to its Muse line. In Artificial Analysis testing, Muse Ember (max) scored 36 on the Intelligence Index, matching Claude Haiku 5.5 (max), while costing an average $0.14 per index task compared with Haiku’s $0.41. The same tests point to a significant trade-off: Muse Ember answered relatively few factual questions correctly and often declined to answer.
Muse Ember is a proprietary Meta model available through Meta’s API and the Muse Code coding agent. It accepts text and images and generates text. Artificial Analysis tested it at two reasoning effort levels: max scored 36 on the Intelligence Index, while xhigh scored 34. The provider’s published figures list a one-million-token context window and output speeds of 440 tokens per second at max and 423 at xhigh.
Artificial Analysis reported an average cost of $0.14 per index task for Muse Ember at max and $0.12 at xhigh. Its reported token prices are $0.10 per million input tokens and $0.50 per million output tokens, matching the listed prices for Claude Haiku 5.5 and GPT-6 Luna. Cached input is listed at $0.004, which the source says is 60% below Haiku’s rate. Artificial Analysis attributes Ember’s lower task cost in part to cheaper cached input and its use of roughly a third as many output tokens as Haiku across the index.
Results vary by task. Muse Ember scored 68.1% on AutomationBench-AA, matching Meta’s more expensive Muse Wonder in the reported test and exceeding Haiku 5.5’s 35.4%. It led Haiku on Terminal-Bench 4.0, but trailed it on FrontierCode 2.0. Within Meta’s Muse Code tool, Ember scored 46 on Artificial Analysis’s Coding Agent Index; that result is specific to the agent and setup tested, rather than a general measure of coding ability.
Meta’s Muse Ember Cost and Caveat
Released November 9, 2026, Muse Ember matched Claude Haiku 5.5 on one benchmark at a lower average task cost—but factual accuracy and frequent refusals are important trade-offs.
Lower benchmark cost, same index score
Artificial Analysis reported equal max-effort Intelligence Index scores for Muse Ember and Claude Haiku 5.5, but different average costs per index task.
| Model | Index score | Cost per index task |
|---|---|---|
| Muse Ember (max) | 36 | $0.14 |
| Claude Haiku 5.5 (max) | 36 | $0.41 |
A clear reliability caveat
The benchmark’s factual results make the low task cost only part of the decision.
- High-volume, repeatable tasks
- Extraction, tagging and form filling
- Workflows where cost per task matters
- Factual answer quality
- How often refusals interrupt work
- Fallback and human-review costs
Performance varies by task
The shared Intelligence Index score does not mean the models perform alike across every evaluation.
Strong result reported
Muse Ember scored 68.1% on AutomationBench-AA, matching Muse Wonder in the reported test and exceeding Haiku 5.5’s 35.4%.
Mixed comparison
Ember led Haiku on Terminal-Bench 4.0 but trailed it on FrontierCode 2.0. Its Muse Code agent score reflects that tested setup, not coding ability in general.
What businesses should verify
Index results are not a guarantee of cost or performance in a live deployment.
- Test on your own documents, prompts and workflows.
- Track answer quality, refusals, review time and latency.
- Include caching, tool calls and fallback models in total-cost estimates.
- Confirm availability and deployment details for your use case.
Lower Costs, With a Reliability Trade-Off
The results position Muse Ember as a possible option for high-volume, repeatable work where cost per task matters, such as extraction, tagging, form filling and routine steps in an automated workflow. The reported $0.14 versus $0.41 comparison is for Artificial Analysis’s index tasks; it does not establish that a business will see the same savings on its own prompts, data or production setup.
Its pattern of answering less often may also matter for applications where an unsupported factual answer creates risk. Artificial Analysis’s AA-Omniscience test found a 21.1% correct-answer rate for Muse Ember and a 64% refusal rate. Its reported hallucination rate was 17.4%, below Haiku 5.5’s 34.2% in that test. These figures describe one benchmark, not the likelihood of error across all uses. Businesses would need to test whether refusals are useful safeguards or interruptions in their workflows, and provide a fallback when Ember cannot answer.
Products Worth Considering

Shark ZU102 Rotator Pet Upright Vacuum with PowerFins HairPro & Odor Neutralizer Technology, Charcoal
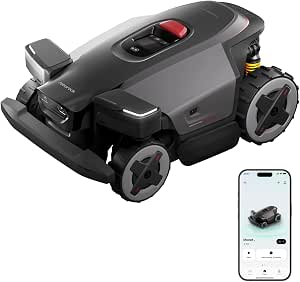
Roborock RockMow X130H Wire-Free 4WD Robot Lawn Mower

Levoit Core 300S-P Smart Air Purifier
As an affiliate, we earn on qualifying purchases.
How the Benchmarks Compare
The Intelligence Index combines nine evaluations, according to the supplied source. A score of 36 places Muse Ember level with Claude Haiku 5.5 in the cited max-effort comparison. The index score does not mean the models perform identically across every task: the reported results differ on automation, document work and coding. Artificial Analysis also places Meta’s Muse Wonder at 44 for $6.95 per index task, while Anthropic’s Claude Fable 5.2 scores 65 at its highest effort level for $26.54 per task.
The comparison is based on Artificial Analysis model pages and data accessed on November 9 and 10, 2026. Its “cost per task” is the average API cost of a task in that index, not a general subscription price or a guaranteed cost for customer applications. The source describes Muse Ember as an efficient tier in Meta’s Muse family and distinguishes it from the higher-scoring, substantially more expensive Muse Wonder.
What the Tests Do Not Establish
The available figures are benchmark results, not independent evidence of performance in live customer deployments. The source does not provide enough detail here to determine how results may change with different prompts, retrieval systems, model settings or user populations. Nor does a lower average cost on the index show that every application will be cheaper: token use, caching, tool calls and the need for human review can affect real-world costs.
It is also unclear how often Muse Ember’s refusals would disrupt ordinary business tasks, or whether a fallback model would erase part of its cost advantage. The supplied material does not include broader customer adoption data, independent production evaluations or details about availability beyond Meta’s API and Muse Code. Those points will need separate confirmation.
Testing Ember in Real Workflows
The next useful evidence will come from task-specific evaluations and production use. Teams considering Muse Ember can compare it with alternatives on their own documents, coding tasks and automated workflows, tracking not just answer quality but refusals, review time, latency and total API cost. Workloads that supply the model with relevant facts may produce different results from open-ended factual questions.
Meta’s API and Muse Code are the access points identified in the source. Further benchmark updates, clearer availability information and independent reports from users could show whether the model’s cost advantage holds beyond Artificial Analysis’s index. Until then, the reported results support a limited conclusion: Muse Ember is inexpensive on that benchmark, but its factual limitations and refusal behavior need to be tested against the job it is expected to do.
Key Questions
What is Meta’s Muse Ember?
Muse Ember is a proprietary Meta model released November 9, 2026. It is available through Meta’s API and in the Muse Code coding agent, and accepts text and image inputs.
How does its benchmark cost compare with Claude Haiku 5.5?
Artificial Analysis reported an average cost of $0.14 per index task for Muse Ember (max) and $0.41 for Claude Haiku 5.5 (max), with both scoring 36 on the Intelligence Index. Those are index-task costs, not a promise about costs for other workloads.
Does Muse Ember answer factual questions reliably?
In Artificial Analysis’s AA-Omniscience test, Muse Ember answered 21.1% correctly and declined 64% of questions. Its reported hallucination rate in that test was 17.4%. These results are limited to the benchmark and do not establish performance on every factual task.
Is Muse Ember better at coding than Haiku 5.5?
The reported coding results are mixed. Muse Ember scored higher on Terminal-Bench 4.0 but lower on FrontierCode 2.0. Its Coding Agent Index score was higher in Meta’s Muse Code setup than Haiku’s score in Claude Code, but that comparison does not establish a general coding advantage across tools and tasks.
Source: ThorstenMeyerAI.com