🔍 Read the full analysis: Three AI Benchmarks Put Claude Fable 5.2’S Progress In Perspective on ThorstenMeyerAI.com

Get the little things that make your day delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
A November 12 analysis of three benchmarks found Claude Fable 5.2 above trendlines for freelance work, general capabilities and simulated robotics. The Remote Labor Index result is the strongest signal; the Epoch score falls within its uncertainty range, while the RoboDojo result comes from Anthropic and is sensitive to the trend method.
An analysis published November 12 found Claude Fable 5.2 above historical trendlines on three AI benchmarks after Anthropic released the model on November 9. The clearest result was on a test of paid freelance projects, while its lead on Epoch AI’s capabilities index was small and within the index’s uncertainty range; the robotics result relies on Anthropic’s own reported score, not a verified leaderboard entry.
The analysis, published by ThorstenMeyerAI.com, says its author retrieved leaderboard data and Anthropic’s launch materials, then rebuilt the trendlines rather than accepting a chart supplied after the release. The method compares Fable 5.2 with historical record-setting models, excluding the new model from each fit. It estimates how far the latest score sits above the projected pace of previous records.
On the Remote Labor Index, Fable 5.2 passed 41.3% of 240 freelance projects, or 99 projects, at a standard described as work a reasonable client would accept. The analysis’s trendline projected 27.2% on the model’s release date, leaving a gap of 14.1 percentage points. It estimates that the historical curve would take about 90 days to reach Fable 5.2’s result.
On the Epoch Capabilities Index, Fable 5.2 scored 173.4 against a projected 171.1, a 2.4-point lead. Epoch’s stated uncertainty range for the model, 169.9 to 177.5, extends below the trend value. On RoboDojo, Anthropic reported a 64.9% success rate on simulated robot tasks. That was 8.8 points above the analysis’s trend fit, but a leaderboard entry for Q0-Preview scored 68.9%, and the analysis says alternative reasonable fits produce a RoboDojo gap from 3.8 to 23.3 points.
Claude Fable 5.2’s benchmark results put in perspective
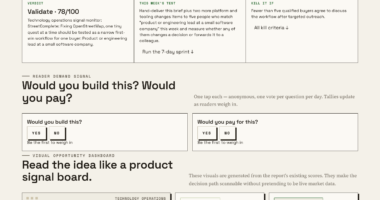
A November 2026 analysis found the model above historical trendlines on three tests, with different levels of confidence. The freelance result stands out; the other comparisons need more caution.
Three tests, different signals
The analysis compared model scores with trends fitted to earlier record-setting models.
Strongest signal
The 41.3% pass rate was 14.1 percentage points above trend. Most tested projects still did not pass.
Lead within uncertainty
The score was 2.4 points above trend, but Epoch’s uncertainty range extends below the projection.
Harder to verify
Anthropic reported a score 8.8 points above the analysis’s trend fit; it is not a verified leaderboard result.
What the freelance test covers
The Remote Labor Index evaluates selected paid projects against a reasonable-client acceptance standard.
How to read the comparisons
Each score was compared with a historical trend fitted without Fable 5.2.
The analysis used historical benchmark record-setters to estimate the prior pace of progress.
It estimated where the trend would sit on Fable 5.2’s release date.
Different fit choices shift the robotics estimate, and the Epoch lead falls within stated uncertainty.
What would clarify the picture
More independently verifiable results could show whether these findings hold across tests and later model runs.
- Look for a verified RoboDojo leaderboard submission and run details.
- Check whether further freelance evaluations reproduce the pass rate.
- See whether future Epoch updates sustain the small lead over trend.
The Freelance Result Stands Out
The results matter because benchmark gains can look more compelling as raw scores than they do against the pace of earlier improvements. The analysis’s comparison suggests Fable 5.2 may have advanced faster than the historical pattern on these tests, but it does not support treating all three results as equally strong evidence.
The freelance benchmark offers the largest and most stable gap in the analysis: under other reasonable fitting choices, its estimated lead remains between 13.0 and 14.4 percentage points. Still, the score should not be read as showing that most freelance work is ready for automation. 41.3% of tested projects met the stated acceptance standard, meaning most did not. The benchmark covers selected projects and does not by itself establish performance across all client work or real-world deployments.
The other two tests warrant more caution. The Epoch lead is small relative to its published uncertainty range. RoboDojo’s score is not a verified leaderboard result, and its estimated distance from trend changes substantially with the fitting method. Together, the benchmarks offer a mixed picture of progress rather than a single definitive measure of what the model can do.
Products Worth Considering

Hisense 55-Inch E6SR Series Hi-QLED 4K UHD Smart Roku TV (55E6SR, 2026 Model)

Philips Hue Play HDMI Sync Box 4K + 65 Play Gradient Smart TV Strip Light

Philips Hue Bridge Pro Smart Lighting Hub
As an affiliate, we earn on qualifying purchases.
How the Trend Comparison Was Built
The analysis compared benchmark record-setters at their release dates, fitting each historical trend without Fable 5.2. It used a logistic curve for percentage-based scores, which cannot exceed 100%, and a straight line for the Epoch index. It then compared the new model’s result with the curve’s projected value on the release date. The author also checked how different fitting choices affected the estimates.
The Remote Labor Index was developed by Scale AI and the Center for AI Safety. Its 240 projects came from 358 Upwork freelancers across 23 job categories, including game development, product design, architecture and data analysis. Scale AI says a human took an average of 28.9 hours per project, with a median of 11.5 hours; the average project was valued at $632.60. Reviewers compared AI work with professional work, and a project passed if the AI’s output met the reasonable-client standard.
For that index, the analysis used 11 record-setters with release dates listed in Epoch AI data, from Gemini 2.5 Pro in June 2025 to Claude Opus 5.5 in September 2026. It excluded four agent products without release dates in that dataset. The Epoch index combines results from more than 50 benchmarks to compare models over time; Epoch cautions that its absolute scores are not meaningful on their own.
Limits of the Three Benchmark Scores
The analysis is not a formal evaluation commissioned or reviewed by the benchmark teams or Anthropic. Its author disclosed that the article was researched and drafted with AI assistance, including Anthropic’s Claude, and said Anthropic, Scale AI, Epoch AI and the RoboDojo team neither reviewed nor sponsored the work. The trendline results are the author’s calculations from available data, not official benchmark findings.
For the Remote Labor Index, the leaderboard provides no confidence interval. The author estimates a rough sampling margin of about plus or minus six percentage points for a 41% rate across 240 projects, and says that would not eliminate the observed gap. That estimate is not an official interval. The analysis also notes that some leaderboard entries lacked release dates and were omitted from the trend fit.
For Epoch, the reported uncertainty range crosses below the trend projection, so the available figures do not establish a clear lead beyond that uncertainty. For RoboDojo, the result comes from Anthropic’s internal run rather than a verified leaderboard entry; the source does not provide enough information to independently confirm the score or resolve why it differs from the higher Q0-Preview entry. The analysis also reports that different trend fits produce substantially different estimated gaps.
Independent Results Would Clarify the Picture
The immediate next step is to look for independently verifiable RoboDojo results and further benchmark entries that make the comparison more direct. A confirmed leaderboard submission for Fable 5.2, together with details on how the run was conducted, could help establish how its reported robotics score compares with Q0-Preview and other systems.
Further Remote Labor Index evaluations could test whether the 41.3% result holds across additional projects and later model runs. Future Epoch index updates may also show whether Fable 5.2’s small lead over the projected trend persists as new models are added. Until then, the analysis supports a strong but bounded result on freelance tasks, a less conclusive capabilities-index comparison and a robotics result that remains difficult to verify.
Key Questions
What did the analysis find about Claude Fable 5.2?
It found the model above fitted historical trendlines on three benchmarks: freelance work, the Epoch Capabilities Index and simulated robotics. The strength of those findings varies by test.
Which result was strongest?
The Remote Labor Index result was strongest in the analysis. Fable 5.2 passed 41.3% of 240 projects, compared with a trend projection of 27.2%, a gap that remained between 13.0 and 14.4 percentage points under other fitting choices.
Does the freelance score mean Fable 5.2 can do most freelance work?
No. It met the benchmark’s reasonable-client standard on 41.3% of the tested projects. Most projects in that set did not pass, and the test does not represent every type of freelance work.
How certain are the Epoch and RoboDojo comparisons?
The Epoch lead was 2.4 points, but Epoch’s uncertainty range extended below the projected trend value. The RoboDojo score was reported by Anthropic rather than verified on the leaderboard, and the estimated lead varies with the trend-fitting method.
Who conducted the analysis?
ThorstenMeyerAI.com published the analysis on November 12, 2026. Its author said the article was researched and drafted with AI assistance, including Claude, and that Anthropic and the benchmark organizations did not review or sponsor it.
Source: ThorstenMeyerAI.com